- The paper introduces FOCUS, a causal-based offline RL algorithm that reduces generalization errors by incorporating structured world models.
- It employs KCI tests to learn and integrate causal structures into model-based RL frameworks, enhancing prediction and policy evaluation.
- Experiments on benchmarks like Toy Car Driving and MuJoCo demonstrate that FOCUS outperforms non-causal methods in robustness and accuracy.
Offline Reinforcement Learning with Causal Structured World Models
Introduction
The paper "Offline Reinforcement Learning with Causal Structured World Models" introduces the FOCUS algorithm, a model-based offline Reinforcement Learning (RL) framework that incorporates causal structures into world models to enhance generalization from historical data without active environment interaction. The efficacy of causal modeling is grounded in theoretical insights demonstrating reduced generalization error bounds. The work proposes FOCUS, illustrating its practical implementation and evaluating it against existing model-based RL approaches.
Theoretical Foundations
Theoretically, the paper establishes that causal world-models reduce generalization errors compared to non-causal counterparts by addressing spurious variable dependencies. It quantifies this advantage in terms of model prediction and policy evaluation error bounds. For prediction, the error bound is expressed as:
E(X,Y)[(∣Y^−Y∣)∣X]≤Xmax∣λi∣(∣γi∣+1)+ϵc
Here, λi represents the coefficient affecting spurious variable influence, γi the strength of correlation with spurious variables, and ϵc the causal prediction noise.
Algorithm Design
FOCUS employs causal discovery techniques (specifically KCI tests) to construct causal structures from offline datasets. The essential steps involve:
- Causal Structure Learning: Utilizing KCI tests to assess conditional independence among variables, forming a causal matrix G.
- Structural Integration: Integrating learned structures into model-based RL frameworks, such as MOPO, to adjust model rollouts and improve policy learning.
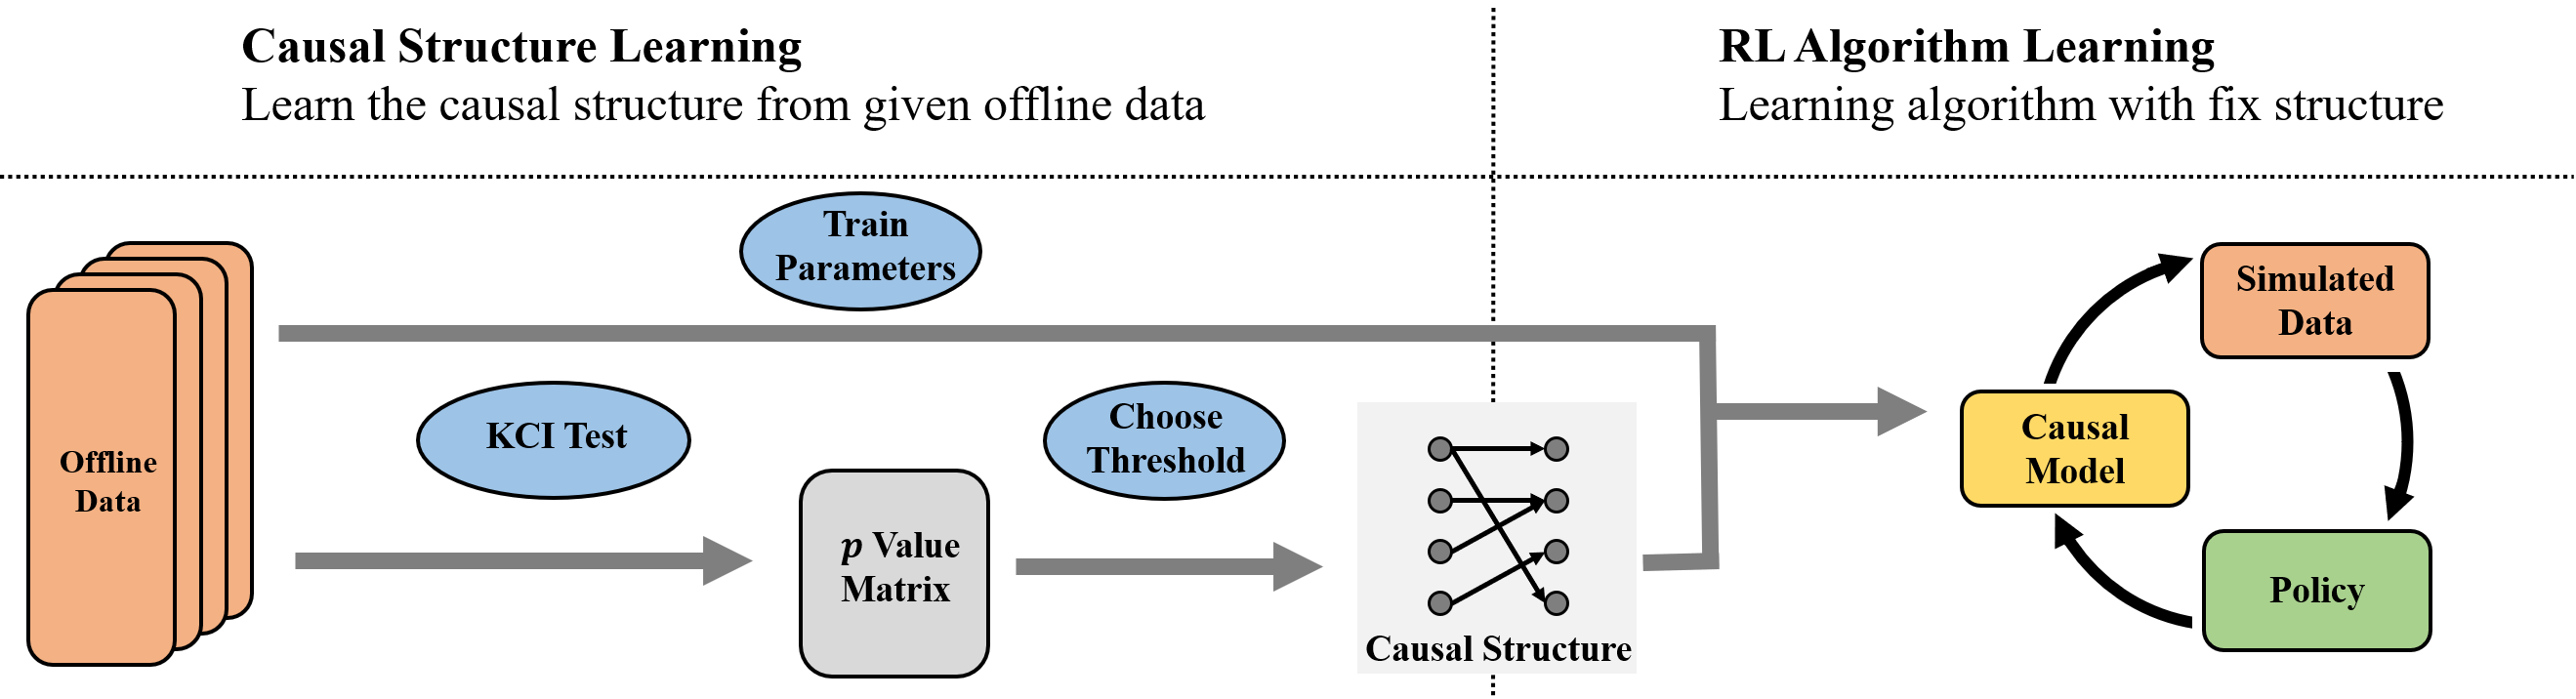
Figure 1: The architecture of FOCUS. Given offline data, FOCUS learns a p-value matrix by KCI test and then derives the causal structure by selecting a p-value threshold.
Experimental Evaluation
Experiments across benchmarks such as Toy Car Driving and MuJoCo environments underscore FOCUS's efficacy:
- Causal Structure Learning: FOCUS achieved high accuracy and robustness in causal graph recovery, outperforming online-based causal learning methods like LNCM, particularly with diverse datasets.
- Policy Performance: Demonstrated significant returns across various data distributions, with marked improvements over models lacking causal integration. Notably, causal-informed policies showed reduced sensitivity to dataset distribution biases.
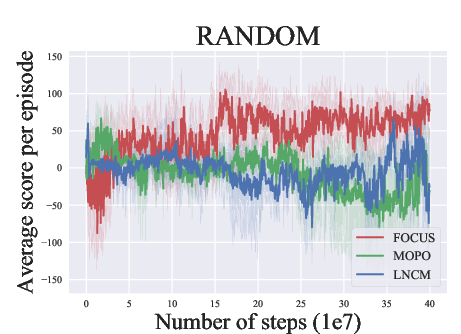
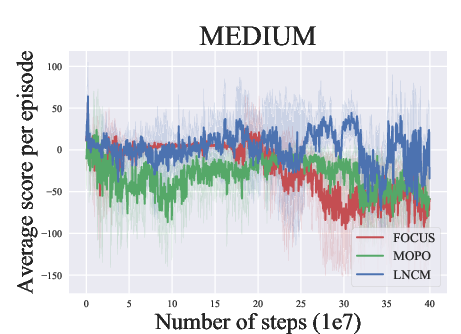
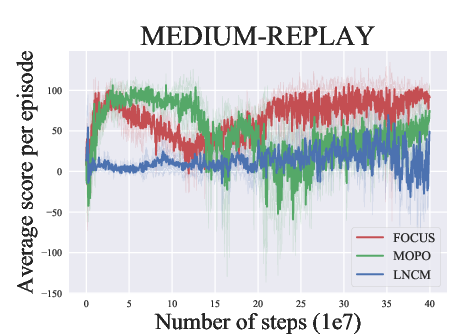
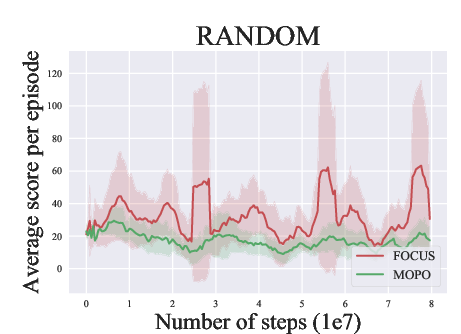
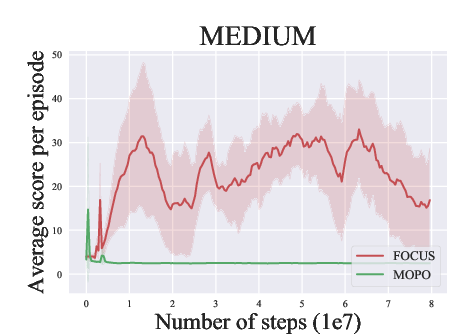
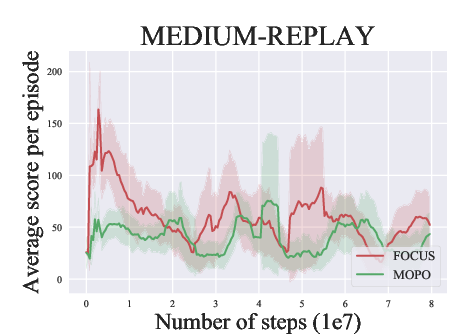
Figure 2: Comparison of FOCUS and the baselines in the two benchmarks.
Implications and Future Work
FOCUS's design illustrates the practical advantages of leveraging causal structures in offline RL settings, emphasizing the potential for improved generalization and robustness in policy performance. Future research avenues include refining causal discovery methods within RL contexts and exploring causal structure uncertainties in complex environments.
Conclusion
The integration of causal structures into offline model-based RL, as exemplified by FOCUS, presents a promising path towards enhanced model generalization, allowing RL systems to derive more reliable policies from static datasets. This research contributes a foundational understanding for further explorations into causal reinforcement learning frameworks.

