Papers
Topics
Authors
Recent
Search
2000 character limit reached

Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks

Published 22 May 2020 in cs.CL and cs.LG | (2005.11401v4)

Abstract: Large pre-trained LLMs have been shown to store factual knowledge in their parameters, and achieve state-of-the-art results when fine-tuned on downstream NLP tasks. However, their ability to access and precisely manipulate knowledge is still limited, and hence on knowledge-intensive tasks, their performance lags behind task-specific architectures. Additionally, providing provenance for their decisions and updating their world knowledge remain open research problems. Pre-trained models with a differentiable access mechanism to explicit non-parametric memory can overcome this issue, but have so far been only investigated for extractive downstream tasks. We explore a general-purpose fine-tuning recipe for retrieval-augmented generation (RAG) -- models which combine pre-trained parametric and non-parametric memory for language generation. We introduce RAG models where the parametric memory is a pre-trained seq2seq model and the non-parametric memory is a dense vector index of Wikipedia, accessed with a pre-trained neural retriever. We compare two RAG formulations, one which conditions on the same retrieved passages across the whole generated sequence, the other can use different passages per token. We fine-tune and evaluate our models on a wide range of knowledge-intensive NLP tasks and set the state-of-the-art on three open domain QA tasks, outperforming parametric seq2seq models and task-specific retrieve-and-extract architectures. For language generation tasks, we find that RAG models generate more specific, diverse and factual language than a state-of-the-art parametric-only seq2seq baseline.

Citations (4,101)

Summary

  • The paper demonstrates the integration of a dense retriever with a seq2seq generator to enhance factual accuracy.
  • It presents two RAG formulations (RAG-Sequence and RAG-Token) that balance consistency and flexibility in language generation.
  • RAG models achieve state-of-the-art results on open-domain QA benchmarks, outperforming traditional extractive methods.

Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks

The paper "Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks" investigates the limitations of large pre-trained LLMs in accessing and manipulating knowledge, especially for tasks requiring intensive knowledge. It introduces Retrieval-Augmented Generation (RAG), which combines pre-trained parametric and non-parametric memory for enhanced language generation capabilities.

Introduction and Approach

Large neural LLMs, despite achieving state-of-the-art results on many NLP tasks, have constraints such as limited ability to expand or revise memory and issues with knowledge provenance. RAG addresses these challenges by integrating a retrieval mechanism with a sequence-to-sequence (seq2seq) generation model. The non-parametric component acts as a dense vector index of Wikipedia, accessed via a pre-trained neural retriever (DPR). The seq2seq generator, specifically BART, then uses these retrieved passages as latent variables in a probabilistic model to generate highly factual, diverse, and specific language.
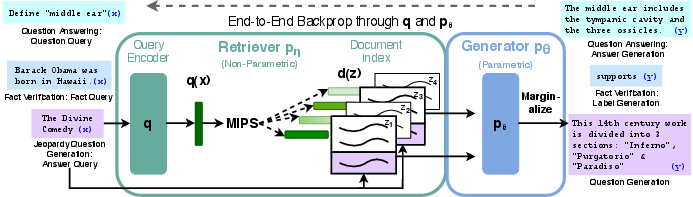
Figure 1

Figure 1: Overview of our approach. We combine a pre-trained retriever~(Query Encoder + Document Index) with a pre-trained seq2seq model (Generator) and fine-tune end-to-end. For query xx, we use Maximum Inner Product Search (MIPS) to find the top-K documents ziz_i. For final prediction yy, we treat zz as a latent variable and marginalize over seq2seq predictions given different documents.

Models and Methods

RAG explores two primary formulations: RAG-Sequence and RAG-Token. RAG-Sequence maintains consistency by using the same retrieved document for generating the entire output sequence, while RAG-Token allows flexibility by permitting different documents for each token prediction. This methodology innovatively addresses the complexity of handling retrieval in generation tasks.

The retriever is based on a bi-encoder architecture from DPR, utilizing BERT\textsubscript{BASE} for producing dense document and query representations. The Maximum Inner Product Search (MIPS) aids in retrieving the relevant documents in sub-linear time.

The generator leverages BART-large, a pre-trained encoder-decoder transformer that models knowledge-intensive tasks by interpolating the input with the retrieved content.

Experimental Results

RAG models achieved state-of-the-art performance on open-domain QA tasks such as Natural Questions, WebQuestions, and TriviaQA, surpassing both parametric-only and task-specific architectures. RAG models demonstrated enhanced performance in language generation tasks, providing more factual, specific, and diverse responses than BART baselines.

(Table 1)

Table 1: Open-domain QA performance metrics, highlighting RAG-Sequence's state-of-the-art results.

In error analysis, it was noted that even when no appropriate documents were retrieved, RAG models could generate correct answers, a significant advancement over extractive models restricted to verbatim extraction from text.

Implications and Future Work

The research presented in this paper highlights the advantages of combining parametric and non-parametric memories in NLP models, demonstrating their applicability across various domains such as QA and generation tasks without relying on task-specific architectures. The findings open avenues for further refinement of hybrid models and exploration of new pre-training objectives that could pre-train both components jointly.
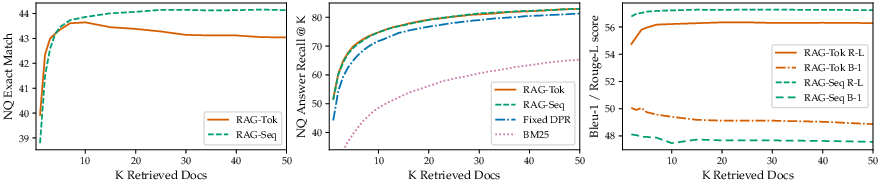
Figure 2

Figure 2: NQ performance as more documents are retrieved, illustrating the model's ability to improve accuracy with increased document retrieval.

Future work may include developing methods that optimize the interplay between these two memory types to further enhance performance on tasks where pre-trained, end-to-end learning offers significant potential.

Conclusion

The paper makes a compelling case for the efficacy of retrieval-augmented generation models in improving linguistic tasks by endowing models with access to external, contextually relevant knowledge. The ability to update non-parametric memory dynamically without retraining signifies a considerable advancement for adaptable and interpretable AI systems, enabling them to perform more robustly in dynamically changing real-world environments.

Paper to Video (Beta)

No one has generated a video about this paper yet.

Whiteboard

No one has generated a whiteboard explanation for this paper yet.

Open Problems

We haven't generated a list of open problems mentioned in this paper yet.

Tweets

Sign up for free to view the 135 tweets with 4494 likes about this paper.

YouTube

Criaram um VÍRUS para atacar Inteligências Artificiais. 371K views
The ChatGPT Paradox: Impressive Yet Incomplete 40K views
RAG w LLM: Dlaczego popularne rozwiązania to droga donikąd? 39K views
Retrieval-Augmented Generation (RAG) 35K views
Lec28 - Retrieval-Augmented Generation (RAG) - Part1 || بالعربي 19K views
#100 Dr. PATRICK LEWIS - Retrieval Augmented Generation 15K views
The scientist who coined retrieval augmented generation 14K views
Bold AI Predictions From Cohere Co-founder 12K views
Lec28 - Part12 - Retrieval-Augmented Generation (RAG) || بالعربي 11K views
Lec28 - Part3 - Retrieval-Augmented Generation (RAG) || بالعربي 10K views
28 – الجزء 4: RAG ببساطة! ما هي Vector Databases وكيف تزود الـ LLM بالمعلومات بدون إعادة Training 10K views
28 – الجزء 5: RAG ببساطة! أفضل Vector Databases في 2025 وكيف تدعم الـ LLM بدون إعادة Training 8.9K views
FREE GPT Researcher AI Agent Powerhouse!🤖Open Source Perplexity Self Hosted - Perplica, Morphic 8K views
6 Years of AI Progress: ModernBERT Finally Replaces BERT 6.3K views
Metric Learning for Images - Keras Code Examples 5.6K views
Chunking in RAG (Retrieval Augmented Generation) with hands-on in LangChain and LlamaIndex 3.7K views
Training Retrieval Augmented Generation With Ola Piktus 2.7K views
LLMs | Retrieval-based Language Models-II | Lec16.2 2.4K views
Reflecting on 5 years of RAG! 2.2K views
Semantic search and RAG 1.9K views
GPT의 할루시네이션을 줄이고 최신 지식을 업데이트 시킬 수 있다고?(RAG)[Retrieval-Augmented Generation for Knowledge-....]-1|꼬꼬엔 1.8K views
Retrieval Augmented Generation: Introduction and Coding 1.7K views
How I Use AutoGen With Retrieval Augmented Generation 1.5K views
LangChain in 257 seconds 1.4K views
Approaching the Competition: Insights and Strategies | DL Sprint 3.0 | Workshop-2 1.1K views
Contextual AI with Amanpreet Singh - Weaviate Podcast #114! 1.1K views
Advanced RAG Techniques 1.1K views
RAG (Retrieval Augmented Generation) explained 1.1K views
What is Retrieval-Augmented Generation (RAG) Architecture? 928 views
Open-Source AI with Vinod Valloppillil and Bob van Luijt - Weaviate Podcast #86! 713 views
The future of SOC with AI Agents - زياد الشهري - www.cognna.com 579 views
Frontiers of GenAI — Foundation LLMs, Grounded LLMs, & Reasoning LLMs • Faculty Lecture @ SDSU 543 views
Opportunities to Refine RAG: Evaluating Your Options 493 views
12 Types of RAG (Part 1 - Original RAG) 482 views
Connor Shorten - PhD Researcher - Florida Atlantic University & Founder at Henry AI Labs 451 views
让机器学会查资料 介绍Retrieval Augmented Generation RAG 407 views
GPT의 할루시네이션을 줄이고 최신 지식을 업데이트 시킬 수 있다고?(RAG)-2[Retrieval-Augmented Generation for Knowledge-....]|꼬꼬엔 356 views
O que é RAG em LLM e AI? Introdução a Geração Aumentada por Recuperação 309 views
🌟 Tercera sesión de TribuAI Papers Fellows 🌟 189 views
RAG 어원 - 2분 요약 185 views
Ep. 5 Tomek Jankowski - Pokora otwiera na rozwój 173 views
Let's Talk about AI Buzzword: RAG | Retrieval Augmented Generation Explained 168 views
Responsible AI in the Era of LLMs and Agents • Guest Lecture at WPI • April 28, 2025 168 views
Building a Retrieval Augmented Generation (RAG) Application with LangChain and Cohere #ai #ml #genai 166 views
AIの能力拡大とAgentモデル – RAG 156 views
15 - The FDA’s Quiet Signal and Why Drug Discovery Is Becoming a Data Business 129 views
Is this IDE the Future of Context-Aware Coding? 120 views
BM126: RAG w LLM: Dlaczego popularne rozwiązania to droga donikąd? 118 views
Mastering Retrieval-Augmented Generation (RAG): A Comprehensive Guide with python Code 111 views